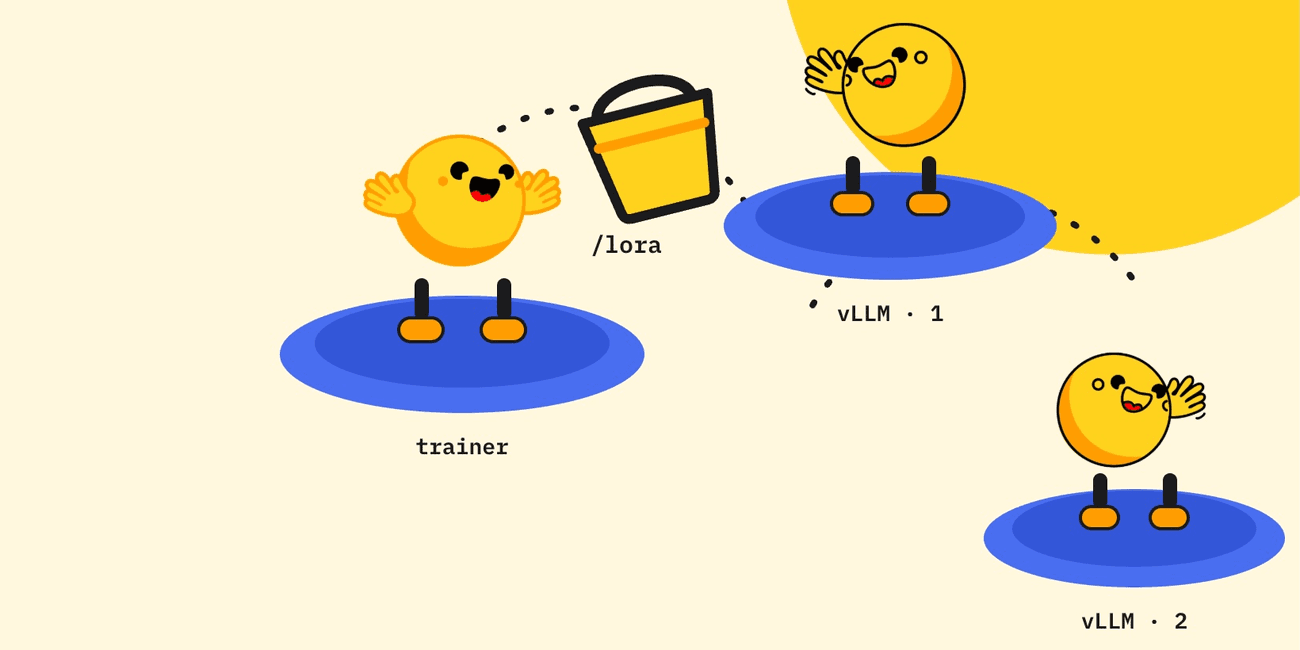
This article explores optimizing asynchronous reinforcement learning training by syncing only lightweight LoRA adapters between the trainer and vLLM inference replicas. By moving from full-weight synchronization to adapter-only updates, the authors enable distributed training across separate compute nodes using storage buckets. The approach utilizes a custom proxy to handle authentication and ensure rollout requests are routed to replicas with the correct adapter state.
Key points
LoRA adapters can match full fine-tuning performance in policy-gradient RL tasks while significantly reducing the data transfer overhead.
Decoupling trainer and inference nodes is feasible by syncing small adapter files via storage buckets instead of using high-bandwidth NCCL clusters.
A proxy layer is necessary to manage adapter propagation and ensure rollout consistency across multiple vLLM inference workers.
Asynchronous trainer architectures allow training and generation to proceed at independent speeds, maximizing hardware utilization in distributed environments.